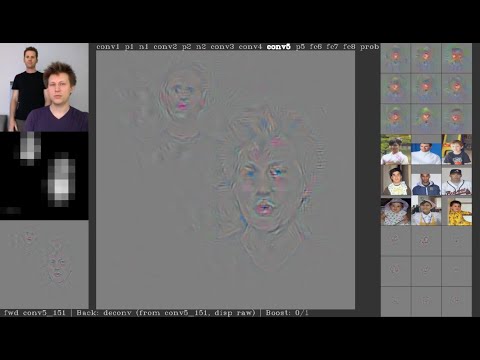
A short demo of the Deep Visualization Toolbox, which shows the activations inside a convolutional neural network as it processes live camera input. Viewers see individual units responding to edges, faces and text.
Why Hacker News points people here: HN points to it as an intuitive way to see what hidden layers of a convnet learn, and as a reference for hierarchical feature learning.
“Highly recommend this video on the Deep Visualization Toolbox”HN comment, 2016
“Highly recommend this video on the Deep Visualization Toolbox”
Understand how convnets work through visualization.
Full comment
Highly recommend this video on the Deep Visualization Toolbox to anyone interesting in understanding more about how convnets work through visualization: this video
Cites itrasmiDec 2016
“you can see neurons that detect edges, faces, and text.”
Shows neurons detecting edges, faces and text.
Full comment
This toolbox allows you to visualize what neural networks "see" at each layer, and what image patterns activate what sorts of neurons (and how). For example, in this video [1] you can see neurons that detect edges, faces, and text. [1] this video
Cites itgnramiresAug 2020
“For example, using feature map and kernel visualization.”
And it also suffers from the tired assumption that GPT-3 (or any language models) should, or are designed to in any way, give reasonable answers[1]. All GPT-3 does is give likely continuations , given the training corpus. The prompts here are too short, and it could likely just be writing mediocre fiction continuations. Fiction tends to not be reasonable much of the time (to create story conflict). > "To understand why, it helps to think about what systems like GPT-3 do. They don’t learn about the world—they learn about text and how people use words in relation to other words. What it does is something like a massive act of cutting and pasting, stitching variations on text that it has seen, rather than digging deeply for the concepts that underlie those texts." This is another pet peeve of mine. It has long been shown experimentally[1] that neural networks such as image recognition and text prediction networks such as GPT-3 do understand deep concepts that underlie texts (not perfectly yet, of course), from emergent abstractions and similar cognitive tools employed by human brains. [1] Gwern has also written extensively on failures of proper prompt programming: link [2] For example, using feature map and kernel visualization. In object classification or detection CNNs, specialized filters arise for detecting common observed object classes, like faces. Moreover, there is a hierarchical assembly of objects from elementary components (e.g. from lines, to limbs, to humans). Dee
Cites itjychangAug 2025
“it's clearly capability that a smaller model cannot demonstrate”
Demo of a neuron lighting up on faces, showing capability needs model size.
Full comment
Why not? It takes models of a certain size to contain xyz neuron/feature. this video That's not a mirage, it's clearly capability that a smaller model cannot demonstrate. A model with less parameters and less hidden layers cannot have a neuron that lights up when it detects a face.