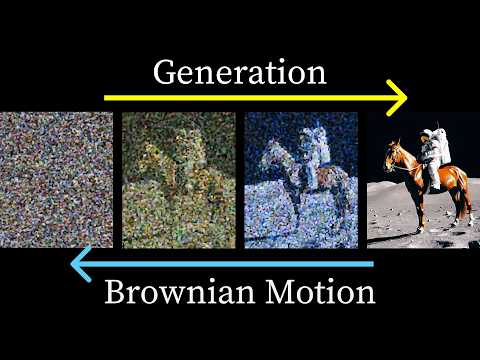
A guest video by Welch Labs on 3Blue1Brown explaining how text-to-image and video models work. It covers CLIP, shared embedding spaces, diffusion models (DDPM, DDIM), conditioning, guidance and negative prompts.
Why Hacker News points people here: HN uses it as a clear explainer for diffusion mechanics, such as negative prompts and faster sampling, and for joint text-image encoders.
Nice video on training text and image encoders together.
Full comment
> Because you somehow need a giant training set which describes images in natural language, no? That's definitely one way - they train a text encoder together with an image encoder on a labelled set of images. WL & 3b1b made a nice video on it: this video
Cites itelliottoAug 2025
“they literally subtract the prompt for 'low quality video' from the input, and it improves the quality.”
Shows subtracting the 'low quality video' prompt to improve generation.
Full comment
My favourite instantiation of this weird invocation is from this AI video generator, where they literally subtract the prompt for 'low quality video' from the input, and it improves the quality. this video I've just migrated my AI product to a different underlying model and had to redo a few of the prompts that the new model was interpreting differently. It's not obseleted, just requires a bit of migration. The improved quality of the new models outweighs any issues around prompting.
Cites itpornelSep 2025
“Breakthrough in image generation speed literally came from applying better differential equations for diffusion”
Explains diffusion speedups from statistical mechanics-based differential equations.
Full comment
Breakthrough in image generation speed literally came from applying better differential equations for diffusion taken from statistical mechanics physics papers: this video