
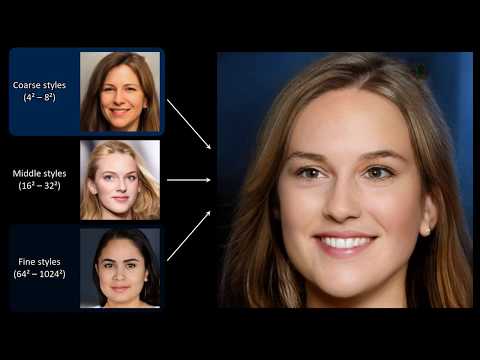
“See this timestamped video for example”
Timestamped demo showing style mixing from reference images.
Full comment
Note that isn't tabula rasa generation. All these faces are generated from reference images. See this timestamped video for example: this video . Current deep generative tech requires a carefully designed dataset of images with controlled variation. For the faces above, a dataset of celebrity faces was carefully constructed from a larger wild dataset, so as to not have any rare features, and the eyes and noses were aligned, making the dataset digestible by a GAN. This particular method then also uses multiple style images which it takes certain features from to mix up and create the mixture face. The main problem with this tech is that the quality can not be reliably controlled. Whatever it generates has to be passed through a human checker/curator pretty much. You can't just serve up generations to the audience without checking what they are. So, imo, this tech would be very useful for the concert art stage of the creative process, being able to just create new things, or mixup existing things, but only to create an intermediate artifact, which would then be used as inspiration for the artists to create the final art. This is also devoid of any form of higher-level reasoning. It doesn't know concepts a human artist would know, such as object permanence, intuitive physics, etc. Something as simple as a ball falling down should squish a certain way, and when hit the ground should squash another way. It also doesn't have artistic sensibilities like anticipation, etc., that have be